Ask Your Data in Plain English: How We Build an AI Reporting Assistant
AI Chatbots and Assistants

- 16 Nov, 2026
- 3 Views
- 0 Comment
By the LaunchLen Web Solutions Team · Last updated: November 16, 2026
When a chatbot answers from your own documents, it doesn’t read the whole library each time. It searches for a few relevant passages and uses those to write its answer. How your documents are split into those passages, called chunks, has a big effect on whether the answer is right.
This post explains the main RAG chunking strategies, what each one is good at and how to test which one works for your content.
What is chunking in RAG?
Retrieval-augmented generation, or RAG, combines a language model with a search step over your own information. The approach was described in the research paper Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks, and it’s now a common way to ground chatbot answers in real documents.
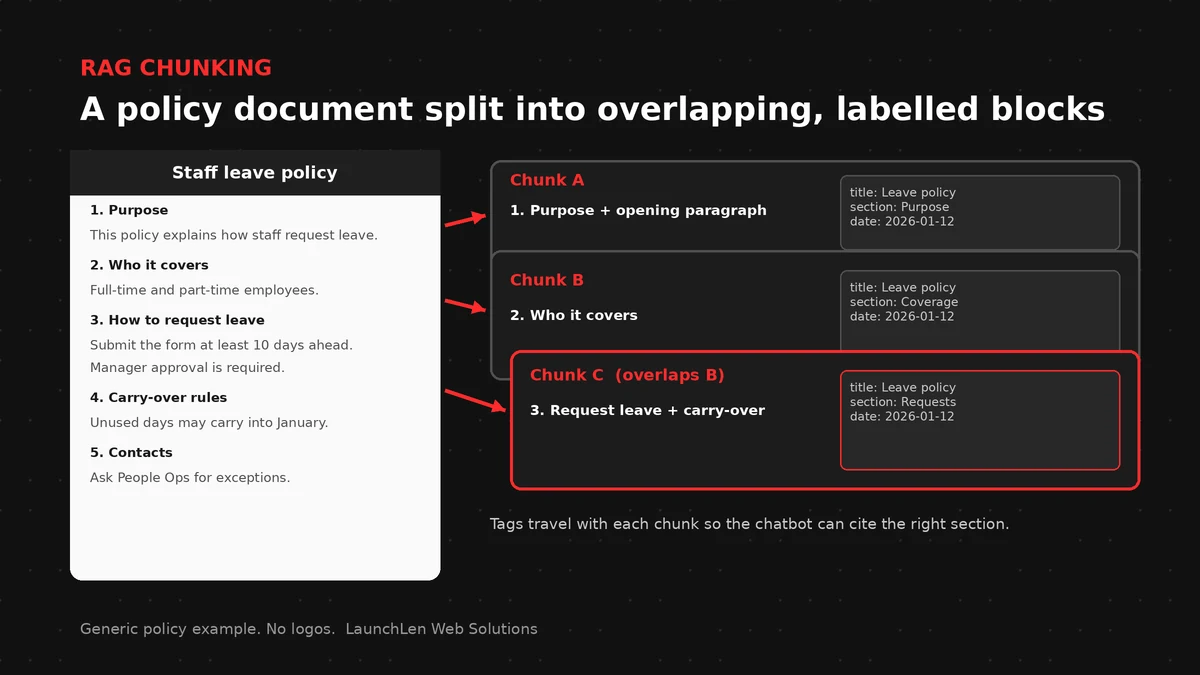
Chunking is the step before search. Each document is split into smaller pieces, and each piece is indexed, often in a vector database, so it can be found by meaning. When someone asks a question, the system retrieves the most relevant chunks and passes them to the model.
Chunks matter for two reasons. Models can only read so much at once, as our post on the context window explains. And each chunk needs to make sense on its own, because the model only sees the pieces that were retrieved.
Microsoft’s documentation on chunking large documents for vector search is one vendor’s written example of these techniques. We cite it as a reference, not as a description of any particular stack.
Fixed-size chunks and overlap
The simplest approach splits text into pieces of roughly equal length. It’s quick to set up and works reasonably well for plain, flowing text.
The weakness is that a fixed split can cut a sentence, a list or an idea in half. Overlap helps: each chunk repeats a little of the text before it, so context carries across the boundary. Too much overlap, though, fills the index with near-duplicates.
There’s no single right size or overlap. Sizes vary by content, so test with your own documents and questions.
Structure-aware chunking: headings, lists and tables
Most business documents already have structure: headings, numbered steps, lists and tables. Structure-aware chunking uses that structure to decide where to split.
- Headings. Splitting at section headings keeps each chunk on one topic.
- Lists and steps. Keeping a set of steps together means the answer doesn’t skip a step.
- Tables. Tables need care. Splitting one in the middle can separate figures from their column labels, so tables are often kept whole or turned into labelled text.
This is one reason clean, well-organized source content matters so much. Our post on preparing content for a chatbot covers how to get documents ready.
Semantic chunking, and when it’s worth the extra work
Semantic chunking looks at meaning rather than length or layout. It groups sentences that belong together and starts a new chunk when the topic shifts.
It can produce more coherent chunks for long, loosely structured documents, such as meeting notes or long reports without clear headings. But it takes more processing to set up and update, and for documents that already have good headings, structure-aware chunking may do just as well. It’s worth testing against the simpler options before committing.
Metadata that travels with each chunk
A chunk on its own can lose important context. Metadata is extra information attached to each chunk, such as:
- The document title, so a chunk from the middle of a policy still says which policy it came from.
- The section heading, so the model knows what part of the document it’s reading.
- A date or version, so newer information can be preferred over older.
- A source link, so the answer can point people to the original document.
Metadata can also help filter results, and it pairs well with hybrid search, which combines keyword and meaning-based search.
Where a passage ends up in the model’s input matters too. The research paper Lost in the Middle found that language models can make less use of information placed in the middle of long contexts. That’s another reason to retrieve a few focused chunks rather than many loosely related ones.
How to test RAG chunking strategies
The only reliable way to choose a chunking strategy is to test it on your own content:
- Collect real questions your customers or staff actually ask.
- Note the right answer and where it lives in your documents.
- Try more than one chunking approach on the same documents.
- Check what gets retrieved, not just the final answer. If the right passage isn’t retrieved, the model can’t use it.
- Compare results and adjust before rolling anything out.
Our post on RAG evaluation explains how to set up this kind of testing. Good chunking helps ground answers, which the Government of Canada’s guide on the use of generative AI describes as having models build responses from only the information you provide and control. Grounding reduces errors but doesn’t remove them, so it works alongside the other methods in our post on how to reduce AI hallucinations.
FAQ
Is there one right chunk size?
No. The right size depends on your documents and the questions people ask. Test a few options with real questions and compare what gets retrieved.
Do tables and PDFs need different handling?
Often, yes. Tables can lose meaning if split in the middle, and PDFs may need their text and layout extracted carefully before chunking.
How do we know whether chunking is causing wrong answers?
Test with real questions and check which chunks were retrieved. If the right passage is missing or cut in half, chunking is a likely cause.
Let’s work together on your project
Planning a chatbot or assistant that answers from your own documents? We’re LaunchLen Web Solutions Inc.
Our AI Solutions page covers how we build AI chatbots and assistants that answer from your content. AI chatbots and assistants we build include full technical support and ongoing SaaS updates.
Serving local businesses across Canada and the US, delivered remotely.
Book a free consultation to get started.
DROP US A LINE
Connect with LaunchLen Web Solutions Inc.
Ready to take the first step towards unlocking opportunities, realizing goals, and embracing innovation? We're here and eager to connect.

To More Inquiry
+1 226 899 4813

To Send Mail